Graph Engineering with AI: A Case from Our Own Operations
Graph engineering with AI is currently an absolute buzzword in the AI world. This real case documents something else: there is nothing mystical about it, and it has nothing whatsoever to do with rocket science. It is simply how you build an AI-supported process today when it has to run unattended.
Graph engineering sounds at first like a category of tools. In fact it is a precise decomposition: work is cut into individual steps, transitions are formulated as logical conditions, and state is stored explicitly. The result is a clearly defined graph of nodes and edges.
The real benefit only shows in the question that cannot even be asked without this decomposition: which node actually needs an AI agent, and which does not? That answer determines cost, runtime and the reliability of an unattended process.
A practical example from our own house shows how this works: a process that has been running since 2 June 2026 and has published on its own twice a day since 26 August.
The case
The AI news page on iconference.ch is not maintained by hand. The source list holds 40 entries, and it splits into two groups that arrive by different routes.
21 sources offer an RSS or Atom feed, among them OpenAI, Google DeepMind and several Swiss trade publications. A Python script fetches these deterministically, with a two-day window and at most five entries per source. Links already seen drop out through a state file. If a source fails, the script skips it and carries on.
The remaining 19 have no feed, the Anthropic news page for instance. For those the script only records a placeholder with the URL. They are fetched one step later by the AI agent, which retrieves the page over HTTP and reads the one to three newest items from it. It also searches the info@iconference.ch mailbox for newsletters.
From these candidates the agent makes its selection and writes the bilingual news entries. After that, code takes over again: merge into a JSON file, build the static pages, commit, push. Two minutes later the content is online. As of today: 607 items from 94 runs.
Nodes, edges, state
The nodes are the concrete work steps: fetch sources, curate, publish.
The edges are deterministic conditions, not mere decorative arrows on a presentation slide. If the draft for a run already exists, the script stops immediately. If the candidates have already been fetched, they are reused rather than requested again. Every one of these rules sits in the script as an explicit check and can be traced.
State lives as a file on disk. That way it survives a crash. An aborted run costs a restart, but no lost work.
Which nodes need an AI
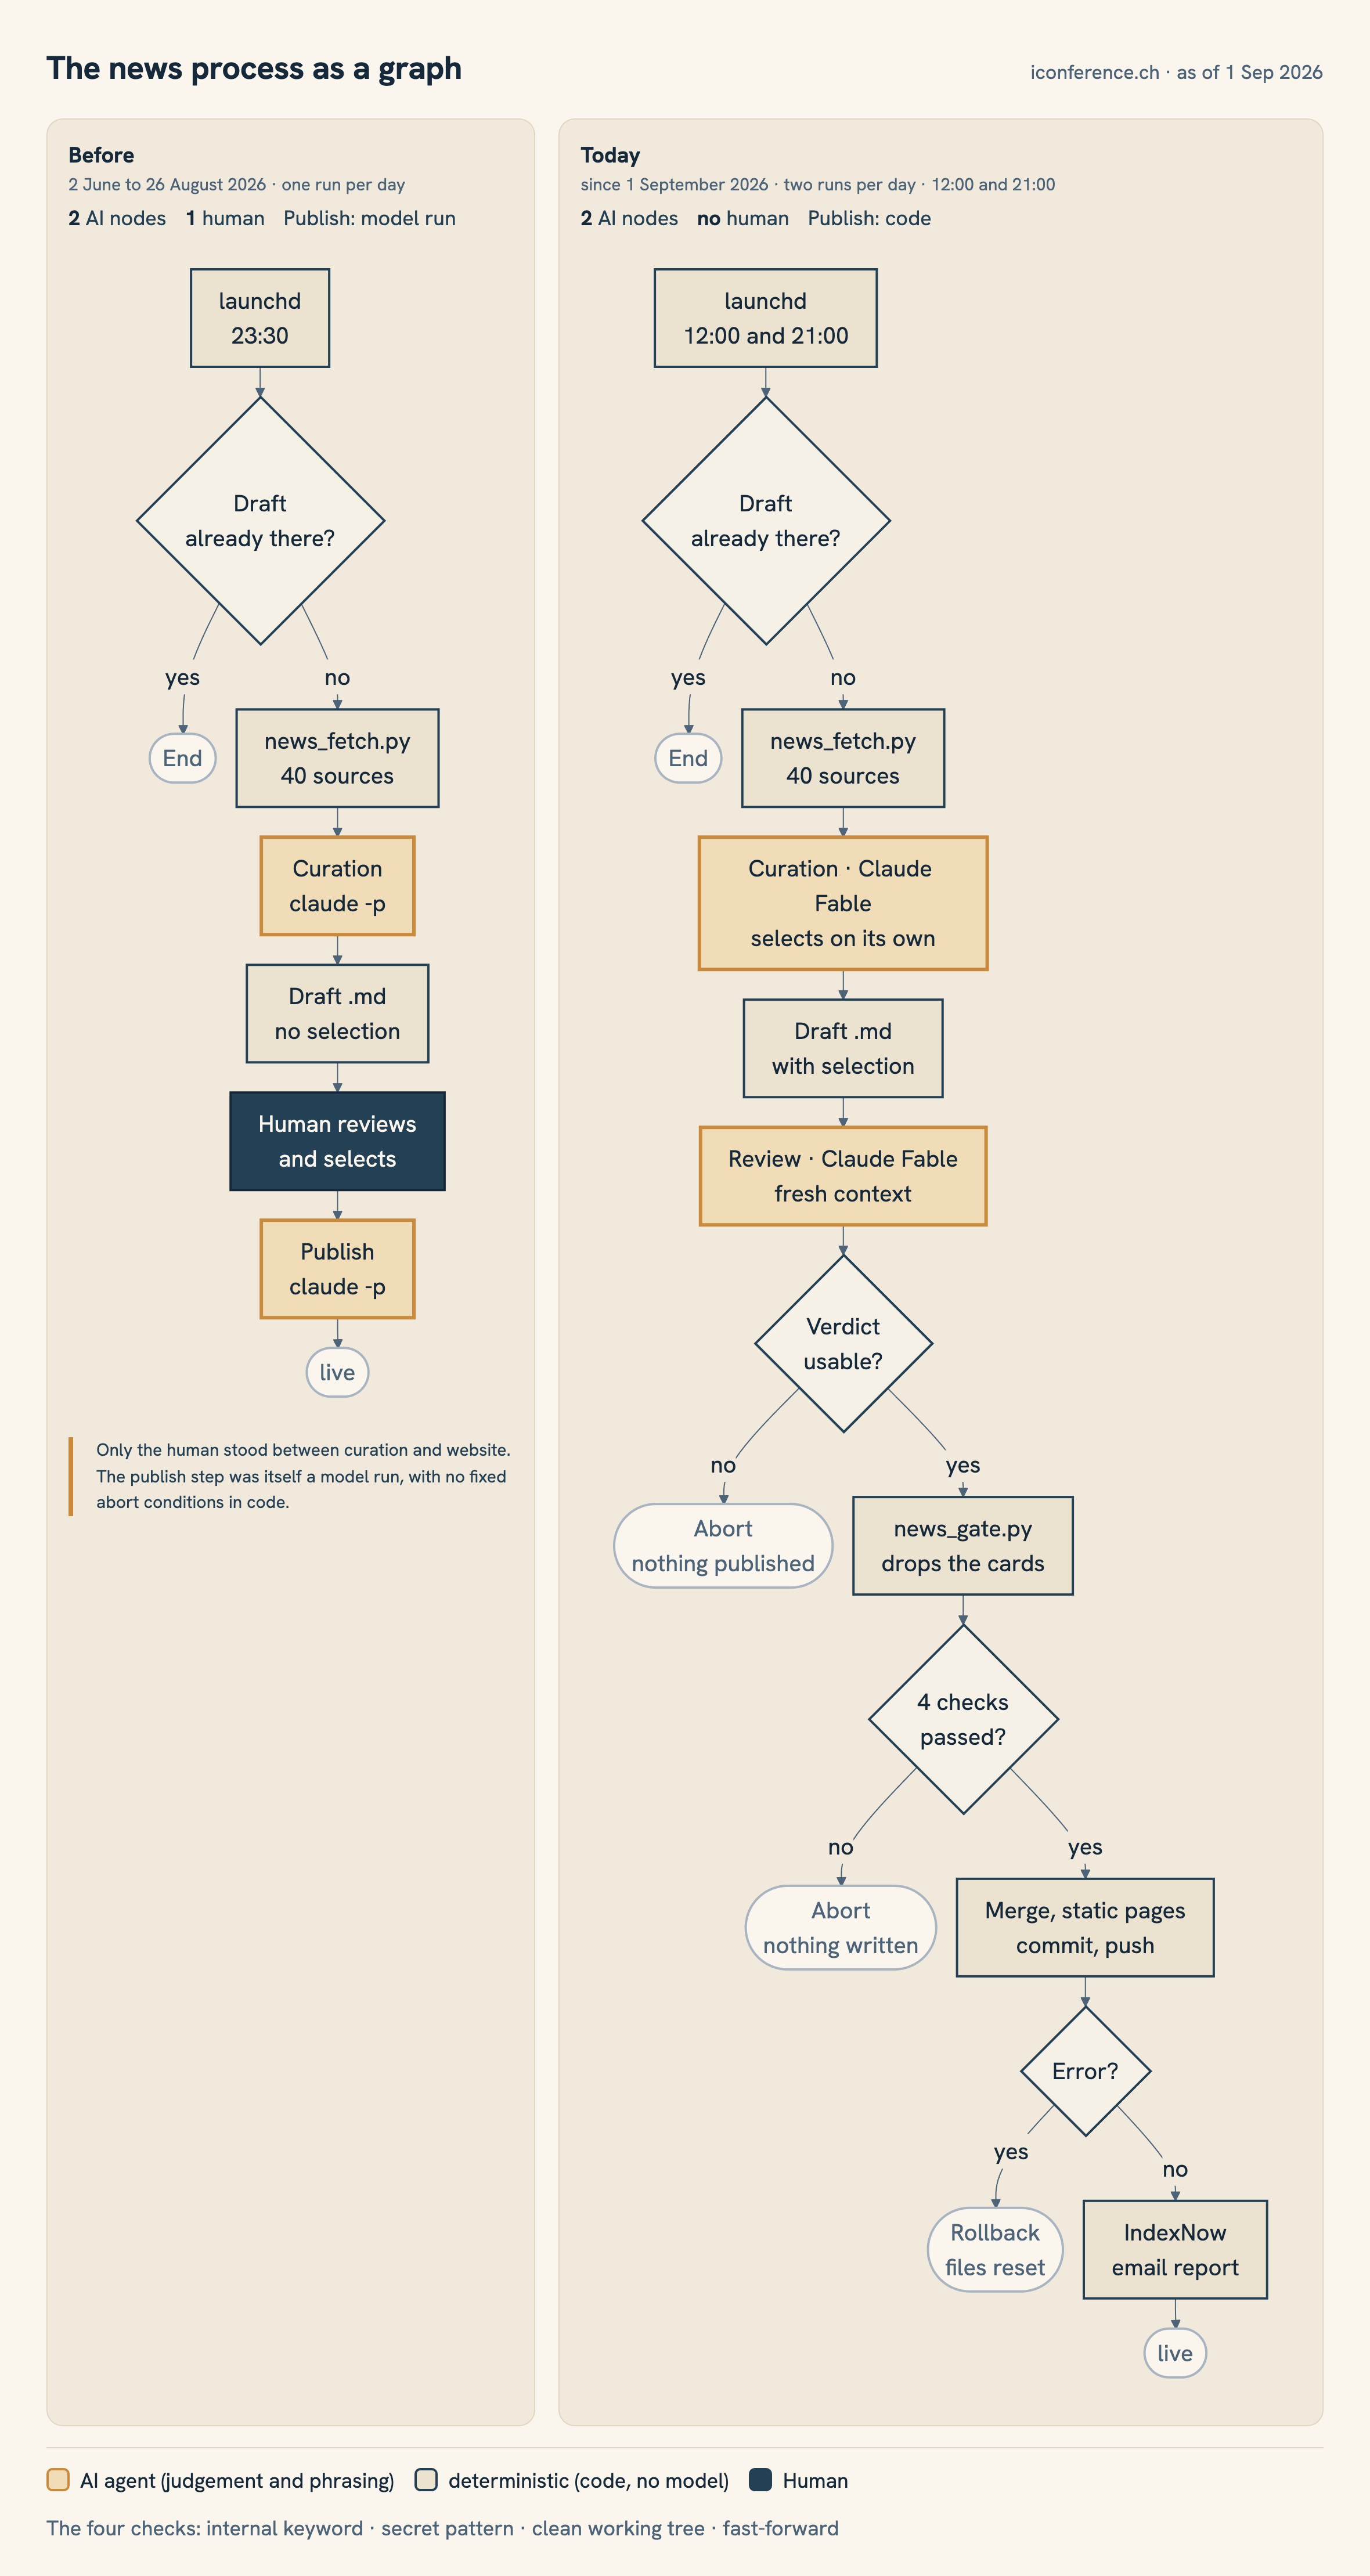
Exactly two nodes in this process require a language model, and they do different things. The first curates: it selects from the candidates and writes the news entries in two languages. No fixed algorithmic rules exist for either, and both call for judgement and phrasing. The second reviews what the first one wrote, and may reject individual entries. Claude Fable handles both nodes, with a pinned model and a tightly restricted toolset.
Before the rebuild there were two model runs as well, but in a different place. Back then the second one wrote instead of reviewing: it carried out the publish step, without fixed abort conditions in code. So the number of model calls today is the same as in June. What changed is their role. One model writes, the other judges what was written, and between them stands Python rather than a human.
The curation node is also the point where foreign text enters the system: feed titles, summaries, entire web pages, none of it vetted. The brief therefore treats that text explicitly as data and never as instruction. The agent follows no call to action from a news item, and the web fetch is limited to the URLs in the source list, never to a URL that appears in the content itself. A process that reads foreign pages and then writes unattended into a Git repository needs that boundary. Without it, one doctored feed entry is enough.
The review node reads that same foreign text a second time, but it has no way out: no web fetch, no connected services, no shell, only reading and writing its verdict file. Nor does it touch the draft. A Python step applies its verdict, removing the ticks and recording the reason. A doctored feed entry can therefore drop an entry through this node at most, never place text on the website. Whoever reviews needs fewer rights than whoever writes.
All remaining nodes work without an AI agent, because they are purely deterministic: fetch feeds, check duplicates against the last 14 days, merge JSON, generate the static pages, run the Git commit and push, and send the status report by email.
The last node is new and looks at first glance like a typical case for an AI. After every run a system email is generated: what went live, which commit hash, how large the total holding now is. Yet no language model is needed for it. The content is fixed the moment the run finishes, and the headlines were written two steps earlier. There is nothing left to phrase, only something to report.
This is exactly where the line runs in practice: it is not «produce text» that requires a language model, but «produce text for which there is no rigid rule».
On paper this decomposition takes half an hour: three columns for nodes, edges and state, followed by the question at each node of whether a simple condition would have done the job. That analysis belongs before the choice of tools, not after.
Who built the graph
I said what should be built and what it had to be able to do. The technical architecture comes from Claude: which node needs a model, which stays deterministic, and where the abort conditions have to sit. Claude then produced the code, meaning scripts, validations and prompts.
Claude therefore has two roles in this project. As the builder it designed and constructed the process. In live operation it is the decision maker at the single node that calls for judgement. That separation is not a detail: the builder worked under my review, the decision maker works without any intervention from me.
My role was that of client and reviewer: judging whether the concept holds, and granting approval. Testing ran against an isolated copy of the directory, covering dry runs, blocked runs, real commits with push, drafts already published, and drafts with nothing selected at all.
86 runs under supervision
From 2 June to 26 August the graph contained one additional node: human approval. The process prepared the draft and stopped. I reviewed the twelve bilingual news entries, made the selection and triggered publication by hand. That phase produced 1052 news entries, of which 550 were published.
The decision to fully automate rested on two factors. The first is capacity: manual approval does not scale, one run a day was the most I could manage, today there are two.
The second was the harder part, namely trust. Across 86 runs I never had to retract a published item: the selection was sound, the translations precise, the publication proposals correct. You do not release an automation with external visibility because the architecture convinces on paper, but because the results hold steady over months. A single flawless run proves nothing at all.
What the automation replaced
When a person reviews a draft, they do two things at once: they catch what must never leave the building, and they judge the quality of the content. To automate that control step, both tasks have to be separated. Hard program code takes over the catching, while the quality judgement is passed to the AI through sharpened prompts and guard rails.
The curation brief to the AI was tightened accordingly:
- At most twelve publications per run.
- A strict block on any warning about dates or duplicates.
- Every discarded entry is marked «not published» along with a one-sentence reason.
- Edge-case rule: when in doubt, an entry stays where it is.
The technical checks before and after generation are handled by Python, not by a language model. The publish step aborts immediately if:
- a text contains an internal keyword,
- the staged diff matches a secret pattern,
- the website repository holds uncommitted changes,
- no fast-forward against origin is possible.
Should anything unexpected happen during the merge, a try/except block automatically resets every file that was touched.
Three mechanisms round out the system, and they inform rather than replace the human. Every unpublished entry carries its reason, which produces a complete trail. After every run the email report arrives. And a published item can be removed afterwards through an ordinary publish.
The first run without approval failed
On 26 August at 12:08 the first unattended run started and failed. The script called node without a full path. Under launchd the default PATH is /usr/bin:/bin:/usr/sbin:/sbin, while node sat in /usr/local/bin. The manual test beforehand had succeeded because it ran in a shell with a complete PATH.
More serious than the error itself was its consequence: the exception had not been caught. The half-merged news.json stayed in the repository, which would have blocked the following run. A failure that drags the next run down with it is no longer a temporary error, it is a standstill.
On 27 August the midday run failed again, this time because of a network fault with failed name resolution across all 21 RSS sources. The evening run picked up the day without trouble, since the time window for candidates spans two days. The two daily slots were originally a capacity decision, but proved to be effective failover.
When approval remains indispensable
This particular process may run without human intervention because four conditions are met at the same time:
- The result is publicly visible and errors are noticed immediately.
- Every step is fully reversible.
- Neither money nor binding commitments depend on it.
- 86 supervised production runs stand as evidence.
If even one of these conditions is missing, human approval remains mandatory. A quotation, a payment, a message to a customer, a change to critical infrastructure: there the actions are irreversible and the risk calculation follows entirely different rules.
Removing the approval from the code was the smaller piece of work. The real achievement was understanding beforehand, precisely, what job it had been doing.
Addendum, 1 September: a second node was added
Two days after this piece was published, a midday run produced three complaints, two of them genuine errors in the published entries. One headline named a law while its own body text spoke of a proposal, and the English version correctly said bill. A second entry left open who was selling what to whom: the headline said one company was buying compute, the body text spoke of a third party backing the infrastructure. Anyone reading only the entry did not understand the story.
Both errors were visible in the draft without opening a single source. That is the point: the curator does not see them, because it wrote them. It knows its own intent and reads it back into its own text. A second pass by the same model in the same context would have changed nothing.
The new node therefore gets a fresh context and sees only what a reader sees: the finished entry. It checks four things, consistency between headline and body, comprehensibility without the source, agreement between the two language versions, and relevance for mid-sized businesses. It may reject, but not rewrite. Whoever reviews and writes at the same time ends up judging their own text.
Measured against the faulty draft, it found both errors and let the other five entries through. One result is missing from that tally: the third complaint was not one. The source name with the typo did not come from our process, it is the publisher's actual domain. Measured, not corrected.
The measurement also showed a limit. On the three hard criteria the node judges consistently, on the softest one it does not: relevance is a judgement call, and the same entry was rejected in one run and passed in the next. That is the price of handing a judgement to a model, and it is bearable here, because the cost of a wrong call is an entry that does not get published rather than a wrong one.
If the review node itself fails, nothing gets published. That is the less comfortable of two options. The other would be to wave things through when in doubt, and then the safeguard would be useless from its first outage, without anyone noticing. A safeguard that quietly stops checking is worse than none.
What would not exist without AI
It is unthinkable that I would have built this process without AI. Running it would be even further out of reach. Neither would have failed on the idea, but on my time and on the missing know-how to program Python and scripts myself.
That is exactly the point of graph engineering with AI: it is not only about making existing processes faster. Processes come into being that were not possible before.
Which business processes in your company could be improved this way, and which would become possible at all?